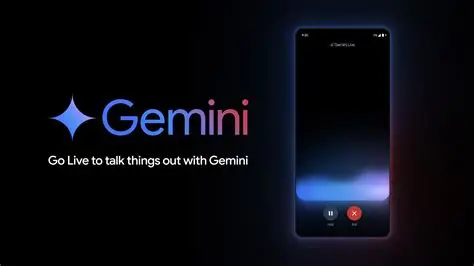
Google has released Gemini 3.8 Live and Gemini 3.8 Live Extended Thinking, two new audio-to-audio artificial intelligence models designed for real-time voice applications.
The models became generally available on September 15, 2026, according to Google’s developer documentation.
Unlike conventional text-based AI systems, the new models are designed specifically for situations where people communicate with AI through spoken conversation.
- That puts low latency at the centre of the experience.
Designed for Real-Time Conversation
A normal AI interaction can involve several stages: speech is converted into text, the text is processed by a language model, and the response is converted back into speech.
Real-time audio systems can make that process feel more natural by handling audio directly.
Gemini 3.8 Live is designed for low-latency audio-to-audio interactions, allowing developers to build voice agents that can respond quickly during conversations.
The system is intended for applications where waiting several seconds for each response would make the interaction feel unnatural.
That could include customer-service agents, voice assistants, educational applications, interactive software and other tools that depend on continuous spoken dialogue.
Extended Thinking Adds Another Layer
Google has also introduced Gemini 3.8 Live Extended Thinking.
The difference is that the Extended Thinking version is designed for situations where the AI needs more reasoning capability during a live audio interaction.
This creates an interesting balance.
Real-time voice applications generally prioritise speed because users expect a conversational response.
More complex reasoning can take longer.
Google’s approach is to provide separate model options so developers can choose between the standard low-latency Live model and the higher-reasoning Extended Thinking model depending on their application.
Asynchronous Tool Use
Another important change is asynchronous function calling.
Google’s developer documentation says asynchronous execution is the default function-calling behaviour in Gemini 3.8 Live.
That matters because voice agents increasingly need to do things beyond simply talking.
A useful AI assistant might need to check information, interact with an external service or perform an action while maintaining a conversation.
Asynchronous processing allows certain operations to happen without completely freezing the conversational flow.
For developers, this could make it easier to build voice agents that feel more like assistants rather than simple speech-based chatbots.
What Developers Can Build
The new models could support a wide range of voice applications.
A company could use them to create an AI customer-service representative that listens to a caller, answers questions and interacts with business systems.
Education companies could build conversational tutors capable of responding to spoken questions.
Developers could also create voice interfaces for software that would traditionally require users to navigate menus and buttons.
The real potential will depend on how well developers combine the model with external tools and their own application logic.
The model itself is only one component of a complete voice agent.
Google’s Competition in Voice AI
The release also places Google deeper into competition over AI-powered voice interfaces.
Companies across the industry are attempting to make AI interactions more natural by combining speech, reasoning, tool use and multimodal capabilities.
The competition is no longer simply about which model can answer written questions most accurately.
Developers are increasingly looking at latency, memory, tool integration, speech quality and how well an AI system can maintain context during extended conversations.
Gemini 3.8 Live therefore represents Google’s attempt to make real-time AI interaction a more practical development platform.
The September 15 release gives developers access to both a standard low-latency model and an Extended Thinking option.
That combination could become particularly important as voice agents move from experimental demonstrations toward applications that need to operate continuously and respond to users in real time.